Bilevel optimization problems are optimization problems whose constraint set is given by the solutions of another, parametric optimization problem. In machine learning and computer vision, they formalize parameter learning: the upper level minimizes a loss that measures the discrepancy between the solution of a model (the lower level problem) and ground truth data, as a function of the model parameters. Applications include the learning of variational models, hyperparameter optimization, and meta-learning.
Gradient-based methods for bilevel problems require the derivative of the lower level solution with respect to the parameters. It can be obtained by implicit differentiation of the optimality conditions, or by replacing the lower level problem with an iterative algorithm and differentiating through its iterations, known as unrolling or automatic differentiation (AD). In practice, the lower level problems are often non-smooth, high-dimensional, and only solved approximately. Our research addresses the central questions behind these approaches: How can non-smooth lower level problems be handled? Does the derivative of the unrolled algorithm converge to the derivative of the solution mapping, and how fast? And how can the memory requirements of AD be reduced?
Partially funded by the German Research Foundation (DFG Grant OC 150/4-1, project Non-smooth Bi-level Optimization for Computer Vision and Machine Learning).
Our Contributions
Bilevel optimization with non-smooth lower level problems
P. Ochs, R. Ranftl, T. Brox, T. Pock
Bilevel Optimization with Nonsmooth Lower Level Problems
In J.-F. Aujol, M. Nikolova, N. Papadakis (Eds.): International Conference on Scale Space and Variational Methods in Computer Vision (SSVM). Lecture Notes in Computer Science, Vol. 9087, 654-665, Springer, 2015. Best Paper Award PDF
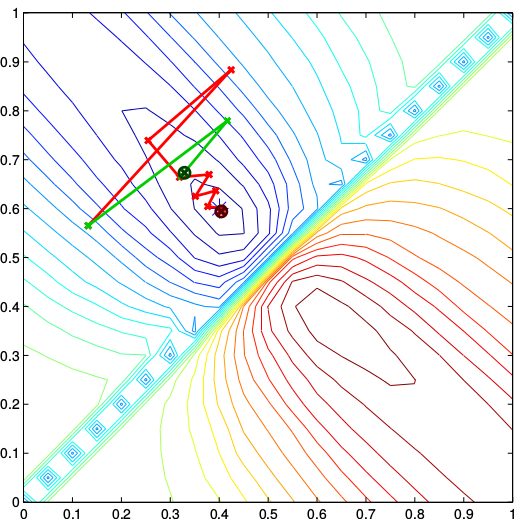
Existing approaches applied implicit differentiation to a smooth approximation of the non-smooth lower level problem. Instead, we proposed to differentiate the iterations of a non-linear primal–dual algorithm, which computes exact (sub)gradients and applies also in the non-smooth setting, demonstrated for multi-label image segmentation. The paper received the Best Paper Award at SSVM 2015.
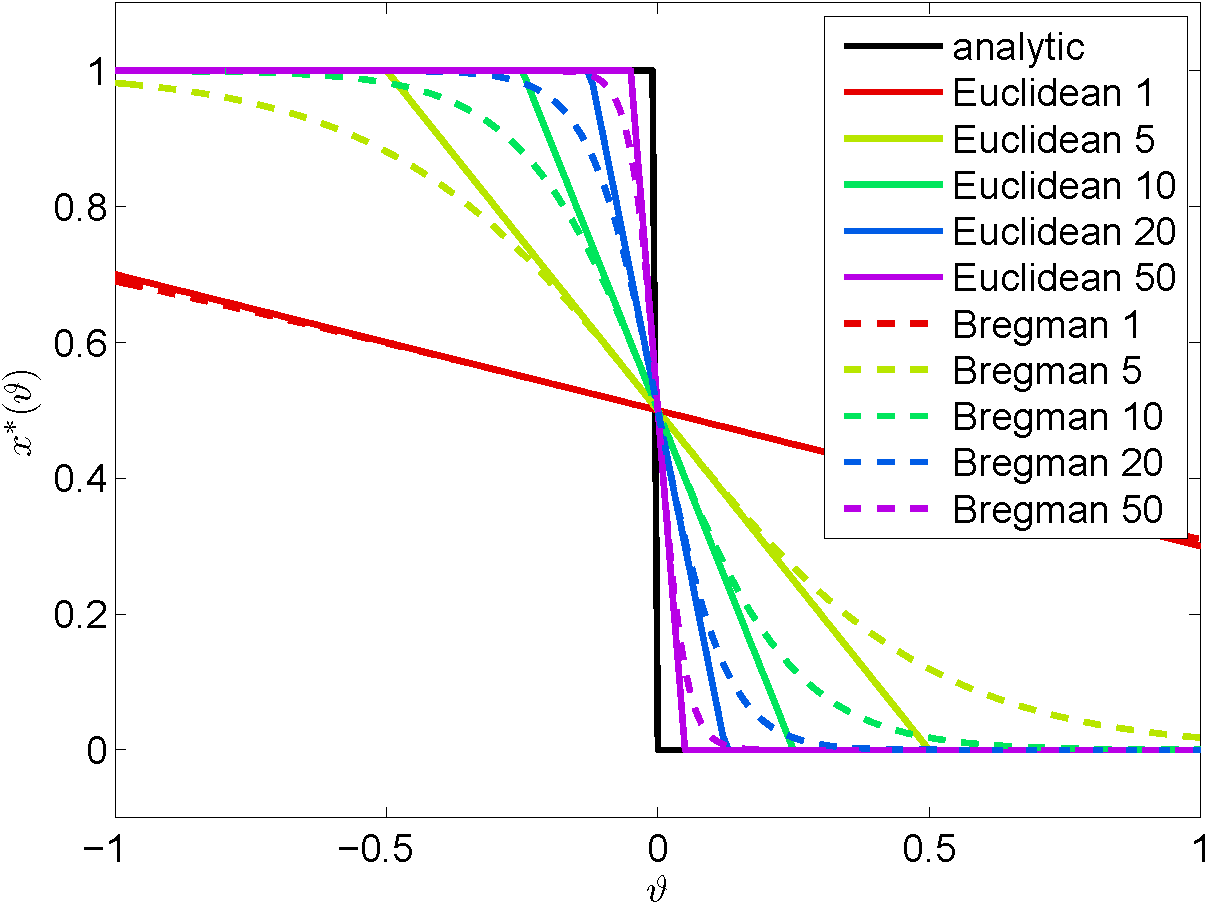
In this invited journal paper, we developed the approach into techniques for bilevel problems with non-smooth and non-unique lower level problems. The lower level problem is replaced by an iterative algorithm that is guaranteed to converge to a minimizer. Using suitable non-linear proximal distance functions, the update mappings of this algorithm are differentiable, although the lower level problem is non-smooth, and the approximation represents the original problem exactly in the limit.
Convergence of automatic differentiation
Unrolling is simple and widely used, but its theoretical foundation has long been incomplete. Our work establishes convergence and convergence rates of the derivative iterates for increasingly general algorithms and problem classes.
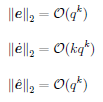
For smooth parametric problems, a class broader than that of strongly convex functions, we proved that if the iterates of an algorithm converge, then the derivatives obtained by AD converge to the derivative of the solution mapping, and we provided convergence rates for both sequences. In particular, the accelerated rate of the Heavy-ball method compared to gradient descent also accelerates the derivative computation.
Many practical problems are non-smooth, but partly smooth
[Lewis02]
A.S. Lewis: Active sets, nonsmoothness, and sensitivity.
SIAM Journal on Optimization 13(3):702-725, 2002.
.
For such problems, proximal splitting algorithms identify the active manifold after finitely many iterations and then converge along it, often with a linear rate
[LFP17]
J. Liang, J. Fadili, and G. Peyré: Activity identification and local linear convergence of forward-backward-type methods.
SIAM Journal on Optimization 27(1):408-437, 2017.
.
Building on this, we proved that AD of proximal splitting algorithms converges to the derivative of the solution mapping. Moreover, we introduced Fixed-Point Automatic Differentiation (FPAD), which remedies the memory overhead of reverse mode AD and comes with a faster theoretical convergence. We demonstrate FPAD by learning the regularization term of an image denoising problem.
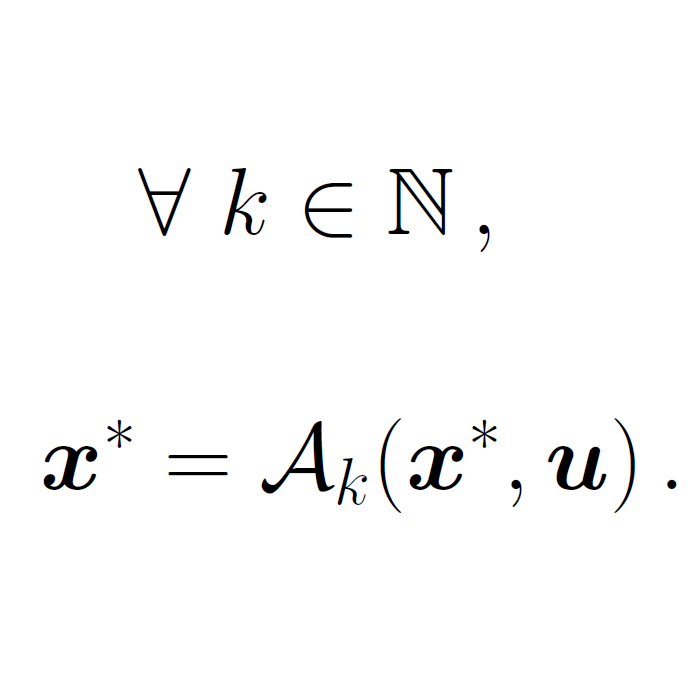
Many optimization algorithms have a time-varying update rule, due to, for instance, a changing step size, momentum parameter, or Hessian approximation. We provide convergence (rate) guarantees for the derivative iterates obtained by unrolling such time-varying iterative processes and apply them to proximal gradient descent with variable step size and to FISTA on partly smooth problems. Theory and experiments show that the convergence rate of the algorithm is reflected in its derivative iterates.
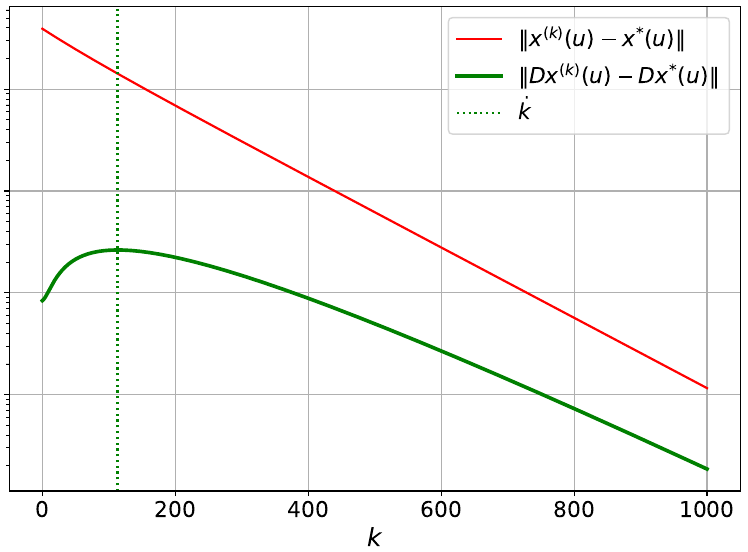
Although the derivative iterates of unrolling converge asymptotically under suitable conditions, they may initially diverge from the true Jacobian, a phenomenon known as the curse of unrolling. We provide a non-asymptotic analysis that explains the origin of this behaviour and identifies the algorithmic factors that govern it. Truncating the early iterations of the derivative computation mitigates the curse and, at the same time, reduces the memory requirements. In bilevel optimization, warm-starting naturally induces an implicit form of truncation, which provides a practical remedy.
Differentiating value functions
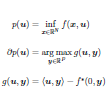
Many problems in machine learning, such as structured support vector machines, matrix factorization, and min–min or minimax problems, require the derivative of the value function of a parametric optimization problem rather than of its solution mapping. Existing approaches rely on strong assumptions on the parametric function. Using convex duality, we relaxed these conditions and derived convergence rates of the derivative approximation for several classes of parametric problems, including non-smooth ones.