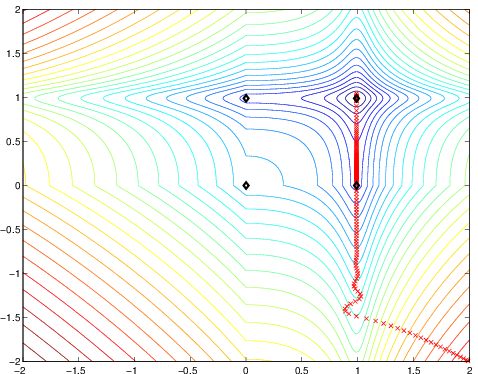
We extended the Heavy-ball method from smooth unconstrained optimization to a class of non-smooth non-convex problems: the sum of a continuously differentiable function with Lipschitz continuous gradient and a non-smooth non-convex extended-valued function with a simple proximal mapping. The algorithm was termed iPiano. We proved global subsequential convergence of the algorithm to a stationary point and, for objective functions that satisfy the Kurdyka--Lojasiewicz inequality, convergence of the whole sequence of iterates. This was the first global convergence result for an inertial algorithm for non-smooth non-convex optimization problems. The Kurdyka--Lojasiewicz inequality is a mild assumption that is satisfied by most functions in practical applications. iPiano has shown state-of-the-art performance for several problems from image processing.
Inertial Algorithms for Non-smooth Non-convex Optimization
Inertial algorithms are motivated by physics, namely by a dynamical system that describes a ball rolling down a surface subject to friction (the heavy-ball dynamical system). The motion of the ball accelerates due to inertia. In analogy, an inertial algorithm adds a fraction of the previous step to the current update, so that the sequence of iterates accelerates when it keeps moving in the same direction. The classic method for smooth unconstrained optimization is the Heavy-ball method, introduced by Polyak in 1964 in a paper with the telling title "Some methods of speeding up the convergence of iteration methods" [Polyak64] B.T. Polyak: Some methods of speeding up the convergence of iteration methods. USSR Computational Mathematics and Mathematical Physics 4(5):1--17, 1964. . The global convergence of the Heavy-ball method for non-convex problems was studied by Zavriev and Kostyuk [ZK93] S.K. Zavriev and F.V. Kostyuk: Heavy-ball method in nonconvex optimization problems. Computational Mathematics and Modeling 4(4):336--341, 1993. . For the mechanical interpretation, we refer to [AGR00] H. Attouch, X. Goudou, and P. Redont: The heavy ball with friction method, i. the continuous dynamical system: global exploration of the local minima of a real-valued function by asymptotic analysis of a dissipative dynamical system. Communications in Contemporary Mathematics 2(1):1--34, 2000. .
In convex optimization, the Heavy-ball method and its variations have led to the study of so-called accelerated schemes and optimal methods [Nesterov04] Y. Nesterov: Introductory lectures on convex optimization: A basic course. Applied Optimization, vol. 87, Kluwer Academic Publishers, 2004. , that is, algorithms whose worst-case complexity is of the same order as the lower complexity bound for a certain class of problems.
Many problems in image processing, computer vision and machine learning, however, are non-smooth and non-convex. Our research in this area started with the question of how inertia can be used in this setting with convergence guarantees, which led to the algorithm iPiano. From there, the thread continued in several directions: general convergence frameworks that cover inertial methods, adaptive choices of the step size and the inertial parameter, also with Bregman distances, and a surprising connection between inertial and quasi-Newton methods.
Our Contributions
iPiano: inertia for non-smooth non-convex problems
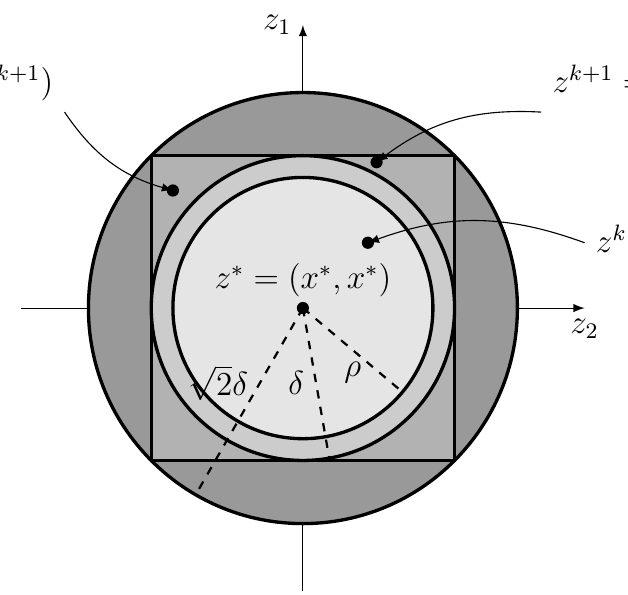
Complementing the global analysis, we studied the local convergence of the Heavy-ball method and iPiano for the class of prox-regular functions. Locally, iPiano is equivalent to inertial alternating/averaged proximal minimization/projection methods, which allowed us to transfer the convergence results, including convergence rates, to these algorithms. Key is a formula for prox-regular functions that expresses the gradient of the Moreau envelope using the proximal mapping, which is well known in the convex setting.
Convergence frameworks for inertial methods
Convergence proofs for algorithms in non-smooth non-convex optimization share a common structure. Abstract convergence theorems capture this structure once, so that new algorithms only need to verify a few conditions. For inertial methods, however, the objective function does not decrease along the iterates, which requires a more flexible framework.
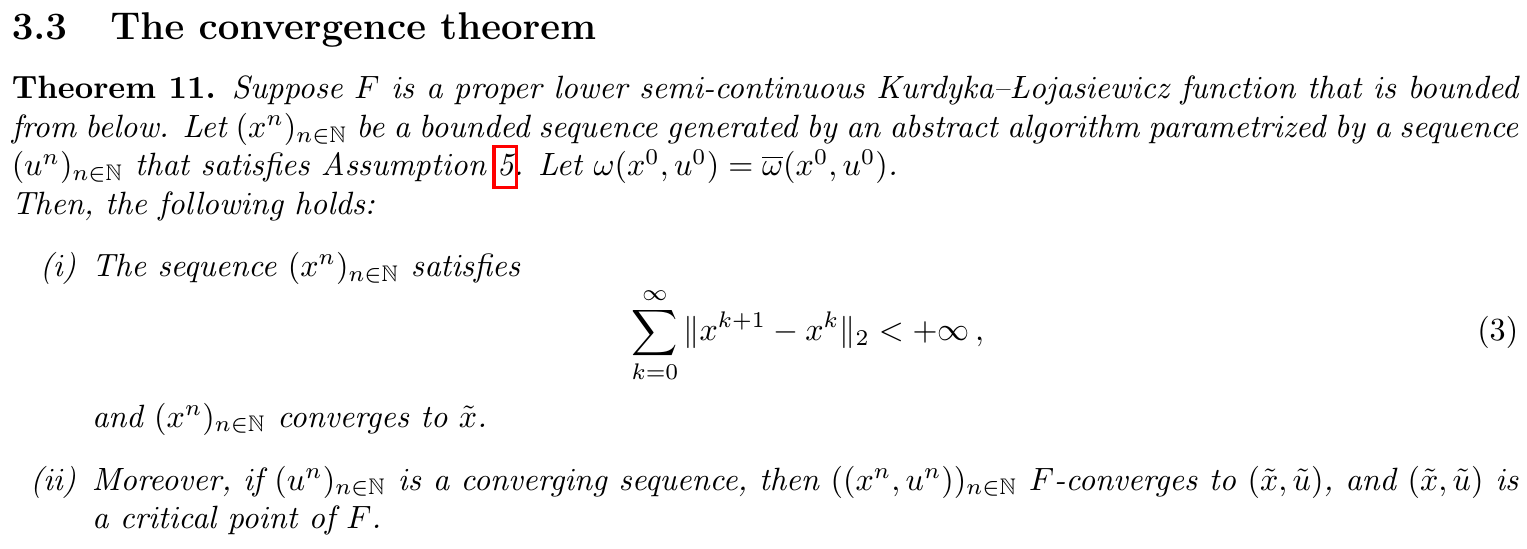
We proved an abstract convergence theorem for Kurdyka--Lojasiewicz functions that unifies several earlier ones. The flexibility that is crucial for inertial methods comes from a descent property with respect to a function that may change along the iterations (instead of the objective itself), a generic distance measure, and relative errors with respect to combinations of distance terms. As an application, we derived a block coordinate and variable metric variant of iPiano. See also our research on the unification of non-smooth optimization algorithms.

Building on this line of work, we introduce an abstract descent scheme that guarantees convergence of the full sequence of iterates to a stationary point for Kurdyka--Lojasiewicz functions and, in addition, allows the update step to be computed inexactly, which is crucial when the proximal mapping has no closed-form solution. Based on this framework, we propose two inertial algorithms: i2Piano, an inexact variant of iPiano that exploits large steps by adapting a local Lipschitz constant, and iPila, an inertial line-search method that enforces descent only on a merit function instead of the objective, which even allows it to escape from local minimizers. Both algorithms inherit the full convergence guarantees of the abstract scheme. Their benefits are demonstrated on image deblurring with impulse noise.
Adaptive extrapolation and Bregman distances
The performance of inertial methods depends crucially on the step size and the inertial (extrapolation) parameter. Fixed choices based on global constants are often overly conservative.
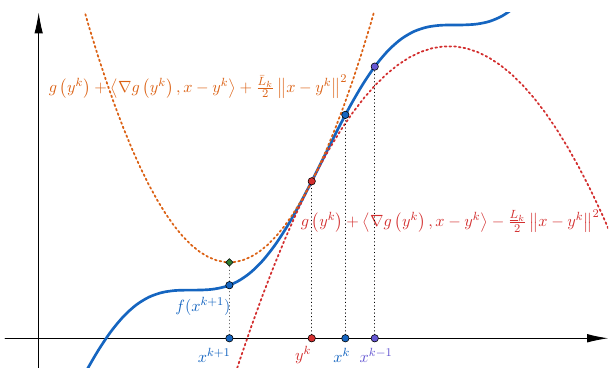
Backtracking finds a suitable step size by locally estimating a simple convex upper bound of the objective function. For inertial methods, this usually leads to very restrictive rules on the extrapolation parameter. We observed that the extrapolation parameter can be controlled by locally estimating also a simple concave lower bound of the objective. The resulting convex--concave inertial (CoCaIn) backtracking strategy adapts both parameters to the "local convexity" of the objective. We apply it to inertial Bregman proximal gradient methods (CoCaIn BPG), which do not require a Lipschitz continuous gradient, and prove the first global convergence result for an inertial algorithm with Bregman distances to a stationary point for Kurdyka--Lojasiewicz functions. The algorithm shows state-of-the-art performance on several problems from machine learning and computer vision.

Bregman proximal gradient methods require a Bregman distance that is adapted to the problem. For matrix factorization, we proposed a novel Bregman distance that allows for closed-form update steps. This enables non-alternating schemes, such as BPG and CoCaIn BPG, for which we prove convergence of the whole sequence to a stationary point. Unlike alternating minimization, they update all factors simultaneously, which avoids a bias towards one of the variables. In several experiments, the non-alternating schemes were superior in terms of speed and objective value at the limit point.

In the same spirit, we developed Bregman distances for training deep linear neural networks, whose loss function does not have a Lipschitz continuous gradient. This yields strong convergence guarantees for BPG and CoCaIn BPG, closed-form updates, and a closed-form expression for the inertial parameter of CoCaIn BPG. Unlike its Euclidean counterpart, BPG requires neither diminishing step sizes nor line search.
Inertial and quasi-Newton methods
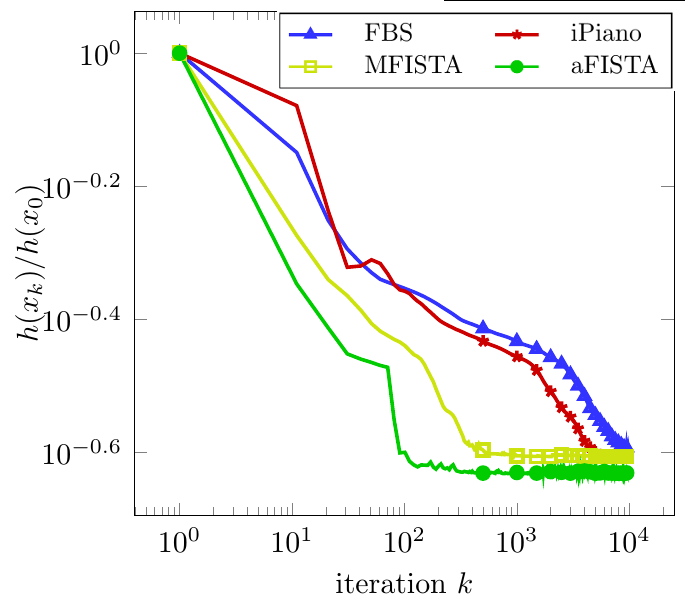
Instead of following a fixed rule, Adaptive FISTA locally optimizes the extrapolation parameter by an exact or inexact line search. Surprisingly, in some situations, the resulting method is equivalent to a proximal quasi-Newton method with an SR1 (identity minus rank-1) metric. Thanks to proximal calculus with respect to a rank-1 modified metric [BF12] S. Becker and J. Fadili: A Quasi-Newton Proximal Splitting Method. In Proceedings of the 25th International Conference on Neural Information Processing Systems (NIPS), 2618--2626, 2012. and its extension to proximal calculus for a rank-r modified metric, the update step can be computed efficiently, also for non-smooth non-convex additive composite problems. Convergence is proved in a general non-convex setting, which, as a byproduct, yields new convergence guarantees for proximal quasi-Newton methods.
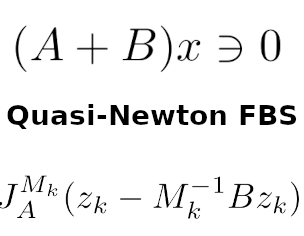
We combine inertia and quasi-Newton metrics in a forward-backward splitting algorithm for monotone inclusion problems. While the inertial step is cheap, the bottleneck is the evaluation of the resolvent operator in the changed metric. We developed an efficient resolvent calculus for low-rank perturbed metrics, which accounts exactly for quasi-Newton metrics, and proved convergence, including linear rates when one of the operators is strongly monotone. As a special case, we obtain an inertial quasi-Newton primal-dual hybrid gradient method for saddle point problems, with favourable performance in image processing. This work is part of the project TRINOM-DS.
Convex setting
With additional knowledge such as strong convexity or a specific problem structure, inertia yields provably faster algorithms.
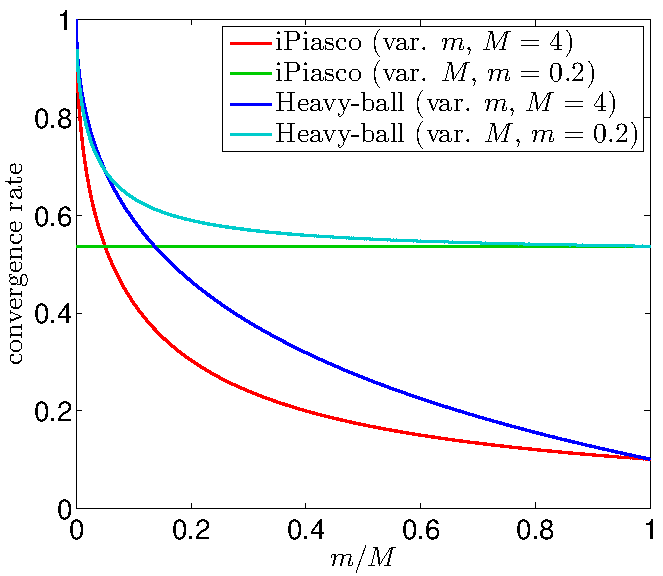
iPiasco is a forward-backward splitting algorithm with an inertial term for strongly convex problems given as the sum of a smooth and a non-smooth convex function. Using the strong convexity, we derived a worst-case linear convergence rate and proved that the algorithm is optimal. For certain problems, this rate is even better than the optimal worst-case rate for smooth strongly convex functions.
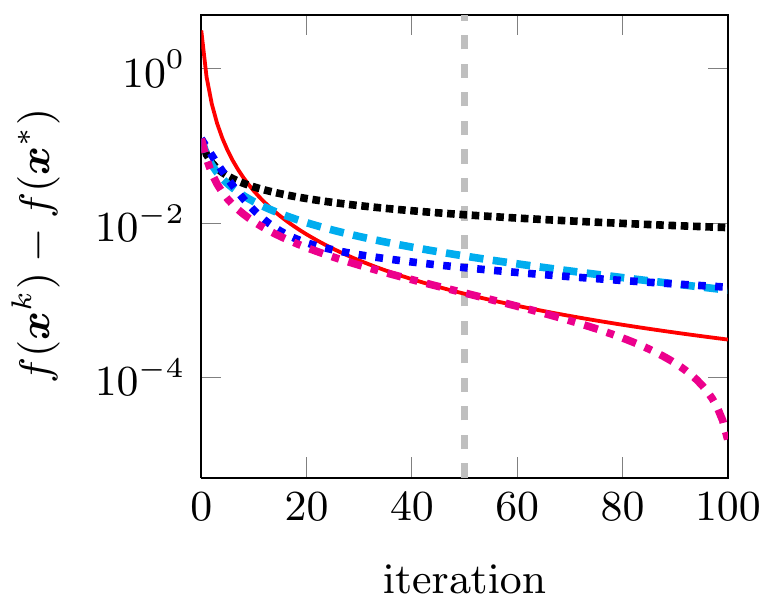
Fast Semi-Iterative (FSI) schemes accelerate basic iterative solvers, such as explicit diffusion schemes, Richardson iterations or projected gradient descent, by extrapolating with the previous iterate. The extrapolation parameters are derived from a connection between box filtering and explicit schemes for 1D homogeneous diffusion, and FSI schemes are closely related to the Heavy-ball method. Applications include anisotropic diffusion inpainting and non-smooth regularization.
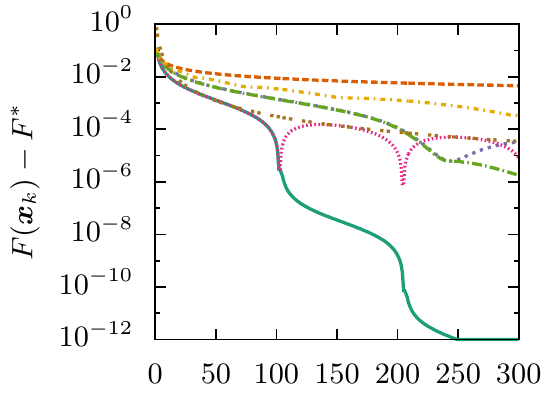
Most acceleration strategies are generic and ignore specific information about the objective function. We equipped FSI schemes with an adaptive restart, which yields a theoretical convergence rate guarantee and state-of-the-art performance on a challenging image processing task.
Continuous-time perspective
Continuous-time dynamics are a powerful tool to understand the mechanics of inertial algorithms. When the step size tends to zero, an inertial algorithm turns into a second-order ordinary differential equation, for example, the heavy-ball with friction system [AGR00] or the ODE that models Nesterov's accelerated gradient method [SBC16] W. Su, S. Boyd, and E.J. Candès: A differential equation for modeling Nesterov's accelerated gradient method: theory and insights. Journal of Machine Learning Research 17(153):1--43, 2016. . In continuous time, the role of each ingredient becomes transparent: inertia carries the trajectory forward, a viscous damping term dissipates energy and governs the speed of convergence, and an additional Hessian-driven damping term reduces oscillations. Lyapunov (energy) functions that prove convergence of the dynamics often serve as a blueprint for the analysis of the corresponding algorithms. We pursue this perspective in our research on the dynamical system view on optimization. The following work connects it directly to inertial algorithms for non-convex problems.
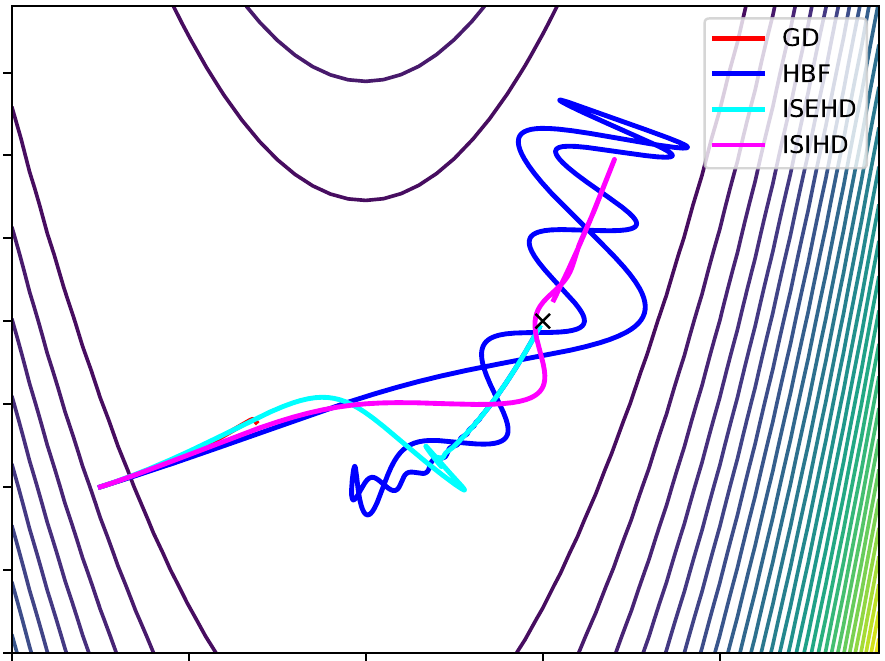
We study non-convex optimization via second-order dynamics with a viscous damping and a geometric Hessian-driven damping. The Hessian-driven damping reduces the oscillations that purely viscously damped systems (such as the heavy-ball system) exhibit near minimizers, without requiring the Hessian to be computed explicitly. For an explicit and an implicit version of the Hessian-driven damping, we prove convergence of the gradient to zero and, for definable objective functions, convergence of the trajectory to a critical point including convergence rates. For Morse functions, the trajectory converges to a local minimizer for almost all initializations. All these properties carry over to the inertial algorithms that result from discretizing the dynamics.