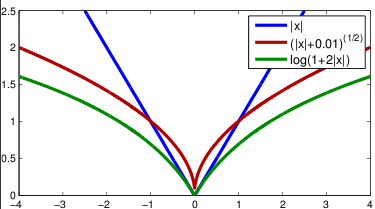
An iterated L1 Algorithm for Non-smooth Non-convex Optimization in Computer Vision
IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2013. PDF
Unification of Non-smooth Optimization Algorithms
Model functions and Bregman distances as a common framework
Many optimization algorithms that look different at first sight rely on the same few mechanisms. We seek to identify these mechanisms and to generalize existing algorithms to frameworks that keep only what is essential for their convergence. This has two benefits: practitioners gain the flexibility to model and solve new problem structures with guarantees, and the frameworks yield insights into existing algorithms and the connections between them.
Two tools are central to this research. Model functions approximate the objective locally, as the linearization does for gradient descent, but they can be adapted to the structure of the problem. Bregman distances replace the Euclidean distance by a distance that is adapted to the geometry of the problem, which removes the common requirement of a Lipschitz continuous gradient. Abstract convergence theorems, finally, capture the common structure of convergence proofs in non-smooth non-convex optimization.
Partially funded by the German Research Foundation (DFG Grant OC 150/1-1, project Unification of Smooth and Non-smooth Non-convex Optimization Algorithms).
Our Contributions
Majorization–minimization and iteratively reweighted algorithms
On iteratively reweighted algorithms for non-smooth non-convex optimization in computer vision
SIAM Journal on Imaging Sciences, 8(1):331-372, 2015. PDF
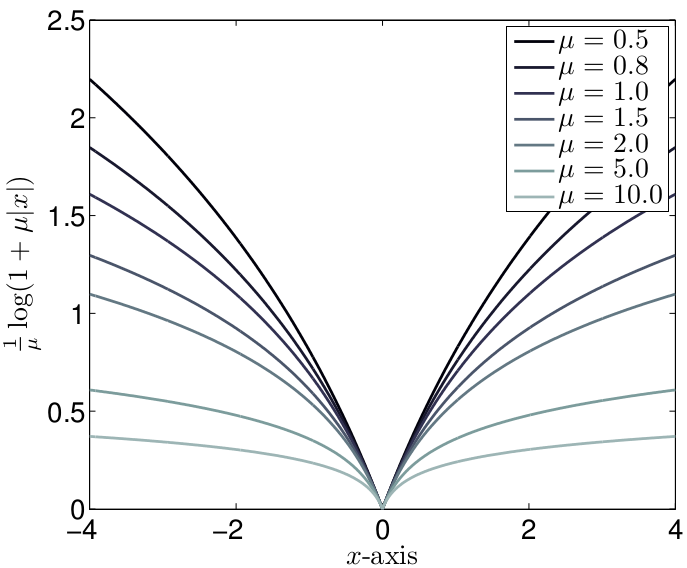
Natural image statistics suggest non-convex regularizers for image processing and computer vision, but they were rarely used in practice because they are hard to optimize. Iteratively reweighted algorithms (e.g., IRLS, IRL1) solve a sequence of convex problems instead. We unified and extended them in a majorization–minimization framework for the sum of a convex function and a non-decreasing (non-convex) function applied to a convex function, which can be implemented efficiently with primal–dual methods. We proved convergence to a critical point under the Kurdyka–Lojasiewicz property. Applications include image denoising, deconvolution, optical flow, and depth map fusion.
Model functions and Bregman distances
Non-smooth Non-convex Bregman Minimization: Unification and new Algorithms
Journal of Optimization Theory and Applications, 181(1):244-278, 2019. PDF
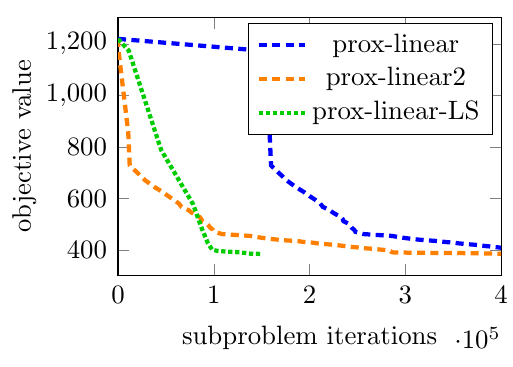
Our model function framework approximates the objective by a convex model function and computes an approximate (Bregman) proximal point of the model. This yields a descent direction, along which the next iterate is found by an Armijo-like line search. Convergence to a stationary point only requires weak assumptions on the growth of the model approximation error. Special instances are gradient descent, forward–backward splitting, and ProxDescent [LW16] A. S. Lewis and S.J. Wright: A proximal method for composite minimization. Mathematical Programming 158(1-2):501--546, 2016. , without the common requirement of a Lipschitz continuous gradient, and the Euclidean distance can be replaced by a broad class of Bregman distances generated by Legendre functions.
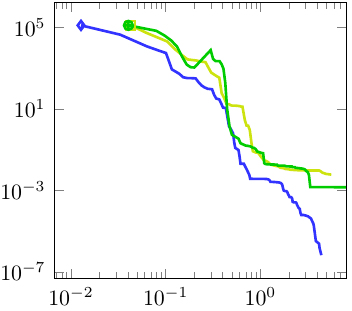
Model Function Based Conditional Gradient Method with Armijo-like Line Search
In K. Chaudhuri, R. Salakhutdinov (Eds.): International Conference on Machine Learning (ICML). Proceedings of Machine Learning Research, Vol. 97, 4891-4900, PMLR, 2019. PDF
In the same spirit, we generalized the conditional gradient (Frank–Wolfe) method to non-smooth non-convex problems by minimizing model functions over the constraint set. Special cases are new algorithms for additive composite problems and for non-linear composite problems, the latter being of Gauss–Newton type, and a hybrid of conditional gradient and proximal minimization that combines the advantages of both.
Global Convergence of Model Function Based Bregman Proximal Minimization Algorithms
Journal of Global Optimization, 83:753-781, 2022. PDF
Line search can be avoided by the relative smoothness (L-smad) property [BBT16] H.H. Bauschke, J. Bolte, and M. Teboulle: A descent lemma beyond Lipschitz gradient continuity: first-order methods revisited and applications. Mathematics of Operations Research, 42(2):330–348, 2017. , [BSTV18] J. Bolte, S. Sabach, M. Teboulle, and Y. Vaisbourd: First order methods beyond convexity and Lipschitz gradient continuity with applications to quadratic inverse problems. SIAM Journal on Optimization, 28(3):2131–2151, 2018. , which generalizes the Lipschitz continuity of the gradient by means of Bregman distances, but does not cover non-smooth functions. We proposed the MAP property, which generalizes the L-smad property to a large class of non-smooth non-convex composite problems, and the globally convergent algorithm Model BPG, which unifies several existing algorithms. The convergence analysis is based on a new Lyapunov function. Inertial variants of Bregman proximal gradient methods are presented on our page on inertial algorithms.
Abstract convergence theorems
Unifying abstract inexact convergence theorems and block coordinate variable metric iPiano
SIAM Journal on Optimization, 29(1):541-570, 2019. PDF
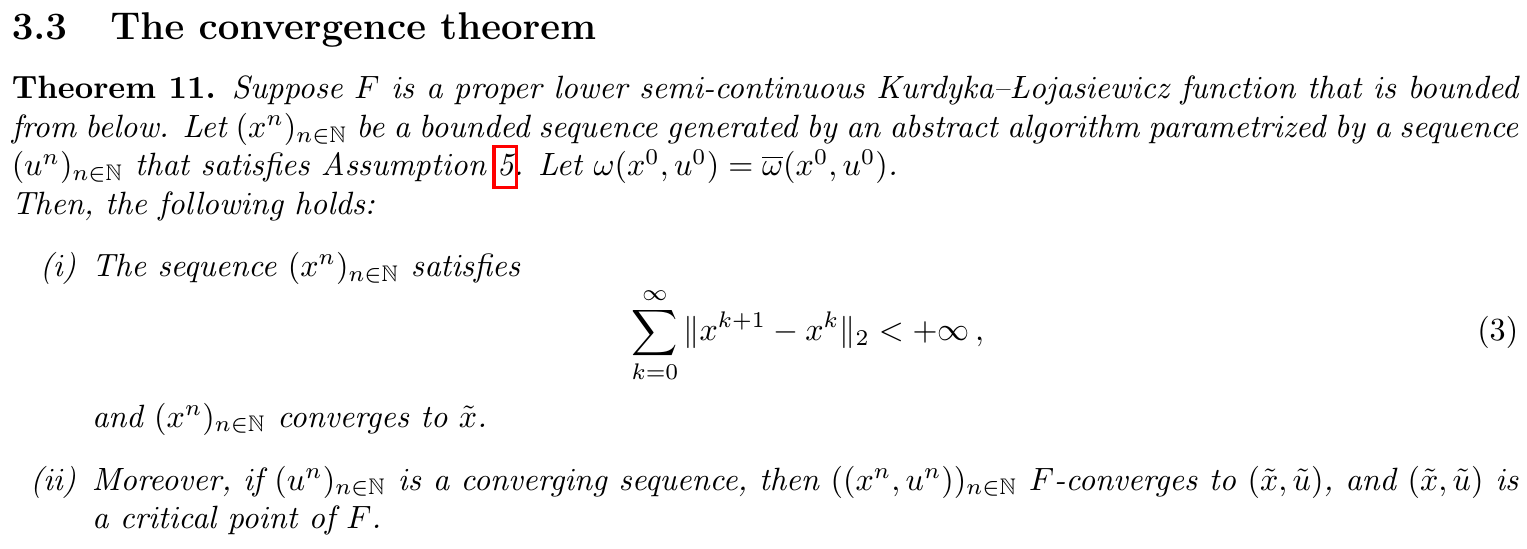
Convergence proofs in non-smooth non-convex optimization based on the Kurdyka–Lojasiewicz inequality follow a common pattern, formalized in the abstract framework of [ABS13] H. Attouch, J. Bolte, and B. F. Svaiter: Convergence of descent methods for semi-algebraic and tame problems: proximal algorithms, forward--backward splitting, and regularized Gauss--Seidel methods. Mathematical Programming 137(1-2):91--129, 2013. : a sufficient decrease condition, a relative error condition, and a continuity condition. Several subsequent works modified these conditions to analyze new algorithms. Our abstract convergence theorem unifies most of these modifications. The decisive generalization is that sufficient decrease is required for a Lyapunov-like, possibly changing function instead of the objective, which is crucial for inertial algorithms (see our research on inertial algorithms). As an application, we derived a block coordinate variable metric version of iPiano.
Bregman proximal calculus and stochastic algorithms

Bregman Proximal Mappings and Bregman-Moreau Envelopes under Relative Prox-Regularity
Journal of Optimization Theory and Applications, 184(3):724-761, 2020. PDF
Bregman proximal mappings and Bregman–Moreau envelopes are the basic objects of Bregman-type algorithms. We systematically studied when the Bregman proximal mapping is locally single-valued and the Bregman–Moreau envelope is locally smooth, under relative prox-regularity, an extension of prox-regularity for non-convex functions that also allows for non-convex domains. As an application, joint alternating Bregman minimization with proximal regularization can be interpreted, locally, as a Bregman proximal gradient algorithm.
Bregman Stochastic Proximal Point Algorithm with Variance Reduction
Technical Report, ArXiv e-prints, arXiv:2510.16655, 2025. PDF
The stochastic proximal point algorithm is more robust with respect to the step size than stochastic gradient descent, but it requires vanishing step sizes. We combine variance reduction with Bregman geometry and propose SAGA- and SVRG-like variance reduction techniques for the Bregman stochastic proximal point algorithm, with improved stability and convergence rates. The analysis also recovers variance reduction for Bregman stochastic gradient descent in a unified way.