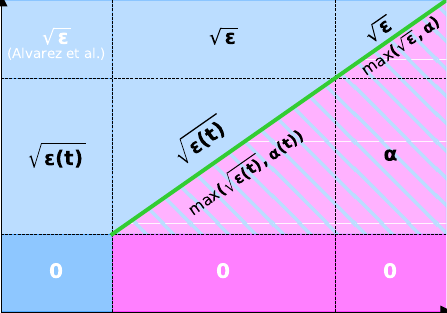
The Dynamical Inertial Newton-like (DIN) family of ODEs [AABR02] F. Alvarez, H. Attouch, J. Bolte, and P. Redont: A second-order gradient-like dissipative dynamical system with Hessian-driven damping: Application to optimization and mechanics. Journal de Mathématiques Pures et Appliquées 81(8):747-779, 2002. mixes inertial gradient descent and Newton's method, positioning it at the interface of first- and second-order optimization. However, most algorithms derived from it behave more like first-order methods. We introduced VM-DIN-AVD, a system with a time-dependent parameter in front of the acceleration, called variable mass, and a damping parameter. It encompasses the main first- and second-order ODEs in optimization as special cases. For strongly convex problems, the variable mass controls non-asymptotically how Newtonian or inertial the system behaves and can turn the dynamics into an accelerated Newton method. We also establish a connection with the Levenberg–Marquardt (regularized Newton) method.
Dynamical System View on Optimization
Many optimization algorithms can be read as time discretizations of ordinary or stochastic differential equations: gradient descent discretizes the gradient flow, and inertial methods such as the Heavy-ball method or Nesterov's accelerated gradient method discretize second-order dynamics with damping [SBC16] W. Su, S. Boyd, and E.J. Candès: A differential equation for modeling Nesterov's accelerated gradient method: theory and insights. Journal of Machine Learning Research 17(153):1--43, 2016. . In continuous time, acceleration, damping and stability appear as properties of a dynamical system rather than as artifacts of a particular discretization. They can be analyzed with tools such as Lyapunov functions, and these analyses provide roadmaps for proving corresponding results for the algorithms.
The ultimate goal of this research is to understand optimization algorithms and to design new ones. The dynamics are therefore not an end in themselves: they explain the mechanisms behind existing methods, for example, the algorithms of our research on inertial algorithms, and they suggest new methods, which we obtain by discretization and equip with theoretical guarantees. Our work covers second-order dynamics that combine inertia with Newton-like and Hessian-driven damping, damping mechanisms that do not depend explicitly on time, dynamics on Riemannian manifolds, and stochastic dynamics that model algorithms with noisy gradients.
Partially funded by the ANR and the German Research Foundation (DFG Grant OC 150/5-1, project TRINOM-DS).
Our Contributions
Inertia, Newton-like and Hessian-driven damping
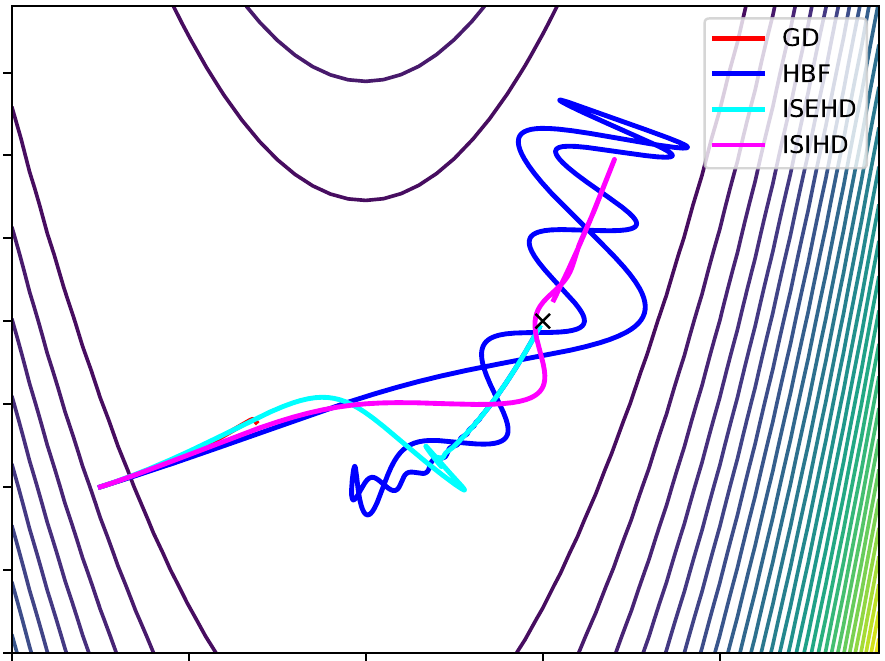
For non-convex problems, we study second-order dynamics with a viscous damping and a geometric Hessian-driven damping. The Hessian-driven damping reduces the oscillations of purely viscously damped systems, without requiring the Hessian to be computed explicitly. For an explicit and an implicit version of the Hessian-driven damping, we prove convergence of the gradient to zero and, for definable functions, convergence of the trajectory to a critical point including convergence rates. For Morse functions, the trajectory converges to a local minimizer for almost all initializations. The same properties hold for the inertial algorithms that result from discretizing the dynamics.
Damping without explicit time dependence
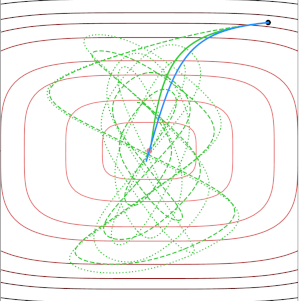
Nesterov's accelerated gradient method corresponds to an ODE with a damping that decreases explicitly with time [SBC16]. Such open-loop damping makes the dynamics non-autonomous, and the arbitrary choice of the initial time influences the trajectory. Replacing it by a closed-loop damping that depends only on the state of the system, while preserving the optimal rate of convergence, is a difficult open problem. We introduced Lyapunov damping, which couples the damping and the speed of convergence via a well-chosen Lyapunov function, and obtained the first autonomous system with closed-loop damping and a rate arbitrarily close to the optimal one. Discretizing the system yields a practical first-order algorithm called LYDIA.
Accelerated dynamics on Riemannian manifolds
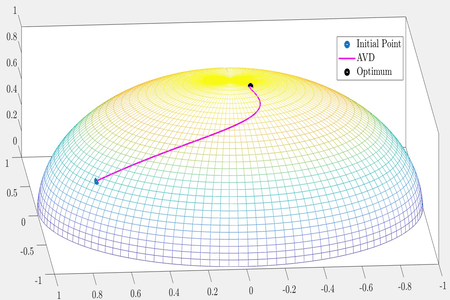
Many problems have a natural non-Euclidean geometry. We study second-order dynamics with an asymptotically vanishing damping for geodesically convex functions on Riemannian manifolds. The curvature of the manifold plays a crucial role in distinguishing the modes of convergence. When the damping parameter exceeds a curvature-dependent constant, we improve the previously known convergence rate of the objective values and prove convergence of the trajectory to a minimizer. Below this constant, the best known rates are transferred from the Euclidean to the Riemannian setting.
Stochastic dynamics
In machine learning, gradients are typically only available up to noise. Stochastic differential equations and inclusions provide a continuous-time model of algorithms with noisy gradient input. The following works develop a systematic theory, from first-order to inertial stochastic dynamics.
We analyze gradient flows under stochastic errors, modelled by a stochastic differential equation whose drift is the negative gradient of a convex objective and whose diffusion term is bounded or square-integrable. We prove almost sure convergence of the objective values and of the trajectory to a minimizer and establish pointwise and ergodic convergence rates in expectation for the convex, strongly convex, and (local) Lojasiewicz case. Extensions cover constrained and certain non-smooth problems.
For composite convex problems with a non-smooth term, we study stochastic differential inclusions driven by the subgradient. We prove almost sure weak convergence of the trajectory to a minimizer and, using Tikhonov regularization with a suitably vanishing parameter, almost sure strong convergence to the minimum norm solution, together with convergence rates in expectation.
Time scaling and averaging allow the properties of first-order dynamics to be transferred to second-order inertial dynamics. We use this principle in the stochastic setting: starting from the first-order stochastic differential inclusions above, we obtain stochastic inertial dynamics with vanishing viscous damping and subgradients in lieu of gradients. Under a mild integrability assumption, the trajectory converges weakly almost surely to a minimizer, with fast convergence of the values and gradients and convergence rates in expectation, including the (local) Polyak–Lojasiewicz case. Tikhonov regularization again yields strong convergence to the minimum norm solution.
We study stochastic inertial gradient dynamics with a time-dependent viscous damping and a Hessian-driven damping, relying on a stochastic Lyapunov analysis. We prove almost sure convergence of the values and fast convergence in expectation. Without Hessian-driven damping, we additionally obtain fast convergence of the values in the almost sure sense and almost sure weak convergence of the trajectory, with pointwise and ergodic rates for the convex and strongly convex case.