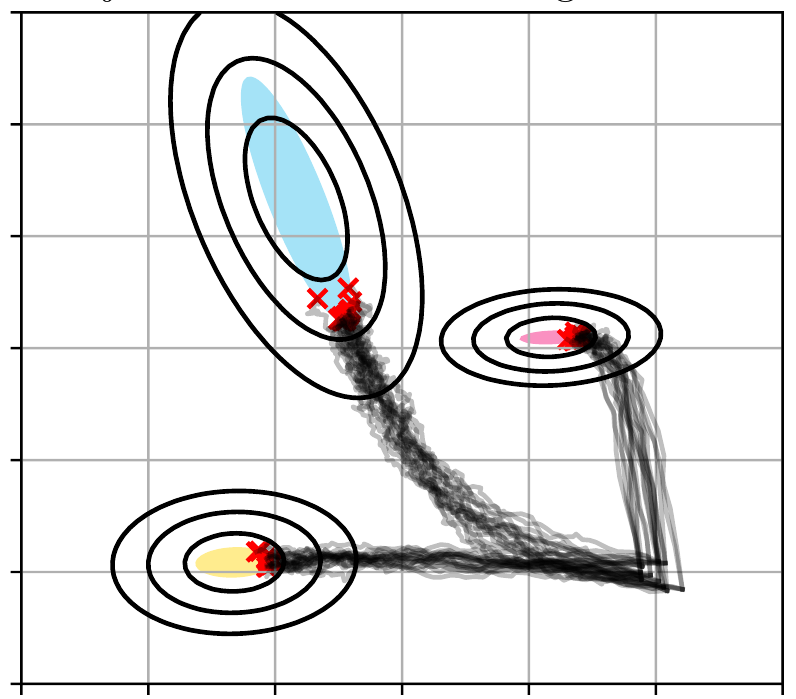
This paper lays the foundation of our approach to learnable optimization algorithms. We propose a statistical-learning framework for optimization algorithms. A distribution over optimization problems together with a learnable optimization algorithm induces a probability distribution over optimization trajectories. Performance is represented by measurable functionals of these trajectories, for example, stopping times, contraction factors, or other trajectory-level properties. This perspective allows optimization performance to be studied at the population level instead of in the worst case, naturally accommodates learning the algorithm from data, and makes statistical-learning techniques, such as PAC-Bayesian generalization guarantees, applicable to optimization-specific performance measures. Experiments on convex, non-smooth, non-convex, and stochastic problems illustrate the statistical nature of optimization performance. It supersedes our earlier preprint "A Markovian Model for Learning-to-Optimize" (2024).
Learnable Optimization Algorithms
Optimization algorithms are the computational engine behind data science, inverse problems, imaging and machine learning. Classically, they are designed analytically: one fixes a class of problems, derives an update rule, and proves convergence and convergence rates in the worst case over this class. This yields robust methods with guarantees for every problem in the class. However, the worst case is rarely the case one faces in practice, and the requirement of analytical tractability severely restricts the design choices.
The field of learning-to-optimize takes the opposite route and lets data shape the algorithm. Learned methods often clearly outperform their hand-designed counterparts on the problems they were trained for, but they typically come without guarantees: whether good performance on the training problems carries over to new problems is, in general, unclear.
Our research develops the foundations of learnable optimization algorithms that combine the strengths of both worlds. The key idea is to treat a learnable optimization algorithm as a statistical object. Optimization problems are drawn from a distribution, the algorithm is a parametric update rule, and its trajectory, and with it any measure of its performance, becomes a random variable. This allows us to ask, and to answer rigorously, questions that are out of reach for a worst-case analysis: How does the algorithm perform on typical problems? How long does it take, on average, to reach a given accuracy? Does the performance observed on finitely many training problems carry over to unseen problems from the same distribution?
Our main tool is PAC-Bayesian (Probably Approximately Correct) learning theory, which turns the empirical performance on training problems into guarantees that hold with high probability for the underlying distribution of problems. Building on this foundation, we study convergence guarantees for learned algorithms, design principles for algorithms that remain reliable beyond their training distribution, and tighter generalization guarantees.
Our Contributions
Foundations: optimization algorithms as statistical objects
PAC-Bayesian learning of optimization algorithms
We introduced the first framework to learn optimization algorithms with provable generalization guarantees. It is based on PAC-Bayesian bounds for general, possibly unbounded loss functions using exponential families, and it makes the trade-off between a high probability of convergence and a high convergence speed explicit. Even in the limit case, where convergence is guaranteed, the learned algorithms provably outperform related algorithms that are derived from a deterministic worst-case analysis. The learning procedure reduces to a one-dimensional minimization problem, which makes it practically realizable.

The journal version develops the framework into a complete methodology. The achieved guarantees depend crucially on the prior distribution, which has to be constructed actively in this setting. We propose concrete design choices for learning optimization algorithms, such as a suitable training loss, and validate the framework in four experiments, ranging from strongly convex smooth problems to non-smooth non-convex problems. The learned algorithms outperform the state of the art by orders of magnitude while their performance remains certified by the generalization guarantees.
Convergence of learned algorithms

Classical convergence guarantees in optimization rely on geometric arguments, which cannot be applied easily to learned algorithms. We developed a probabilistic framework that resembles deterministic optimization and allows geometric arguments to be transferred to learnable algorithms. The main result is a generalization theorem for parametric classes of potentially non-smooth, non-convex loss functions, which establishes the convergence of learned algorithms to stationary points with high probability. This can be seen as a statistical counterpart to the geometric safeguards that are usually employed to enforce convergence. The paper was selected for an oral presentation at ICML 2025.
Beyond the training distribution

Generalization guarantees certify the performance on the distribution of the training problems. Towards learned algorithms that are usable beyond this setting, we identified key principles that classical algorithms obey, but that had not been used for learning-to-optimize. Following these principles, we provide a general design pipeline that takes data, architecture and learning strategy into account, resulting in a philosophy of learning optimization algorithms. As an example, we designed a learning-enhanced BFGS algorithm, which performs well far beyond the problems of its training distribution.
Tighter generalization guarantees
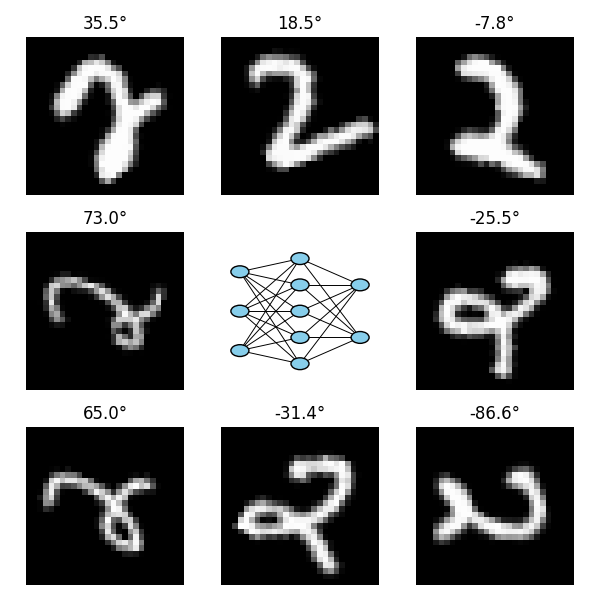
Symmetries are known to improve the empirical performance of learned models, yet theoretical guarantees explaining these gains are limited. Prior work focused on compact symmetry groups and assumed that the data distribution itself is invariant. We extend PAC-Bayesian generalization guarantees to non-compact symmetries, such as translations, and to non-invariant data distributions, and we tighten existing bounds, as demonstrated for McAllester's bound. Experiments on rotated MNIST with a non-uniform rotation group confirm that the guarantees hold and improve upon prior results.
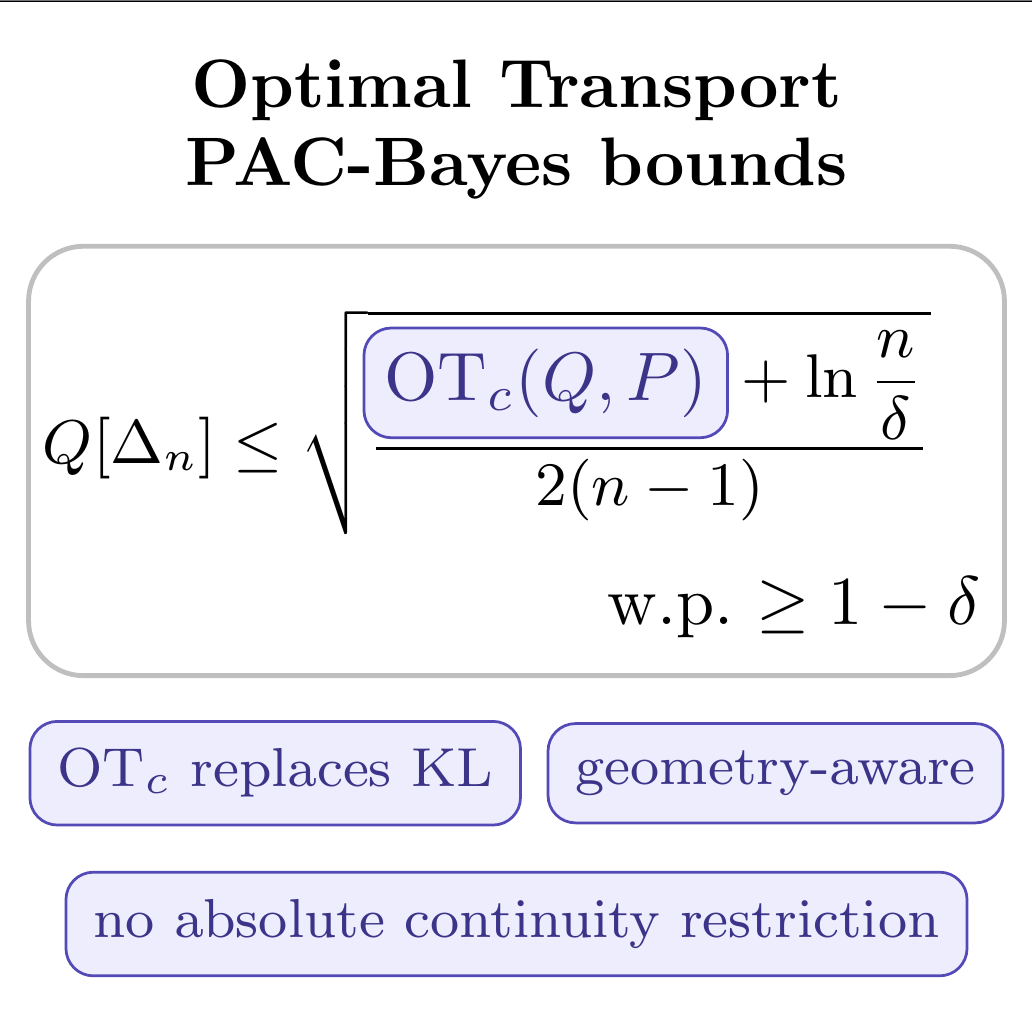
PAC-Bayesian bounds are typically expressed in terms of the Kullback–Leibler divergence between a prior and a posterior distribution. While analytically convenient, it requires the posterior to be absolutely continuous with respect to the prior, which restricts the choice of the posterior substantially, and it does not account for the geometry of the underlying space. We derive new PAC-Bayesian bounds in which the Kullback–Leibler divergence is replaced by general optimal transport distances, including the total variation and Wasserstein-p distances.